What the ad repository ChatGPT has to publish will actually reveal
by Cătălin Popa · updated 2026-09-10
Two things happened seven days apart, and together they change what you can find out about your competition.
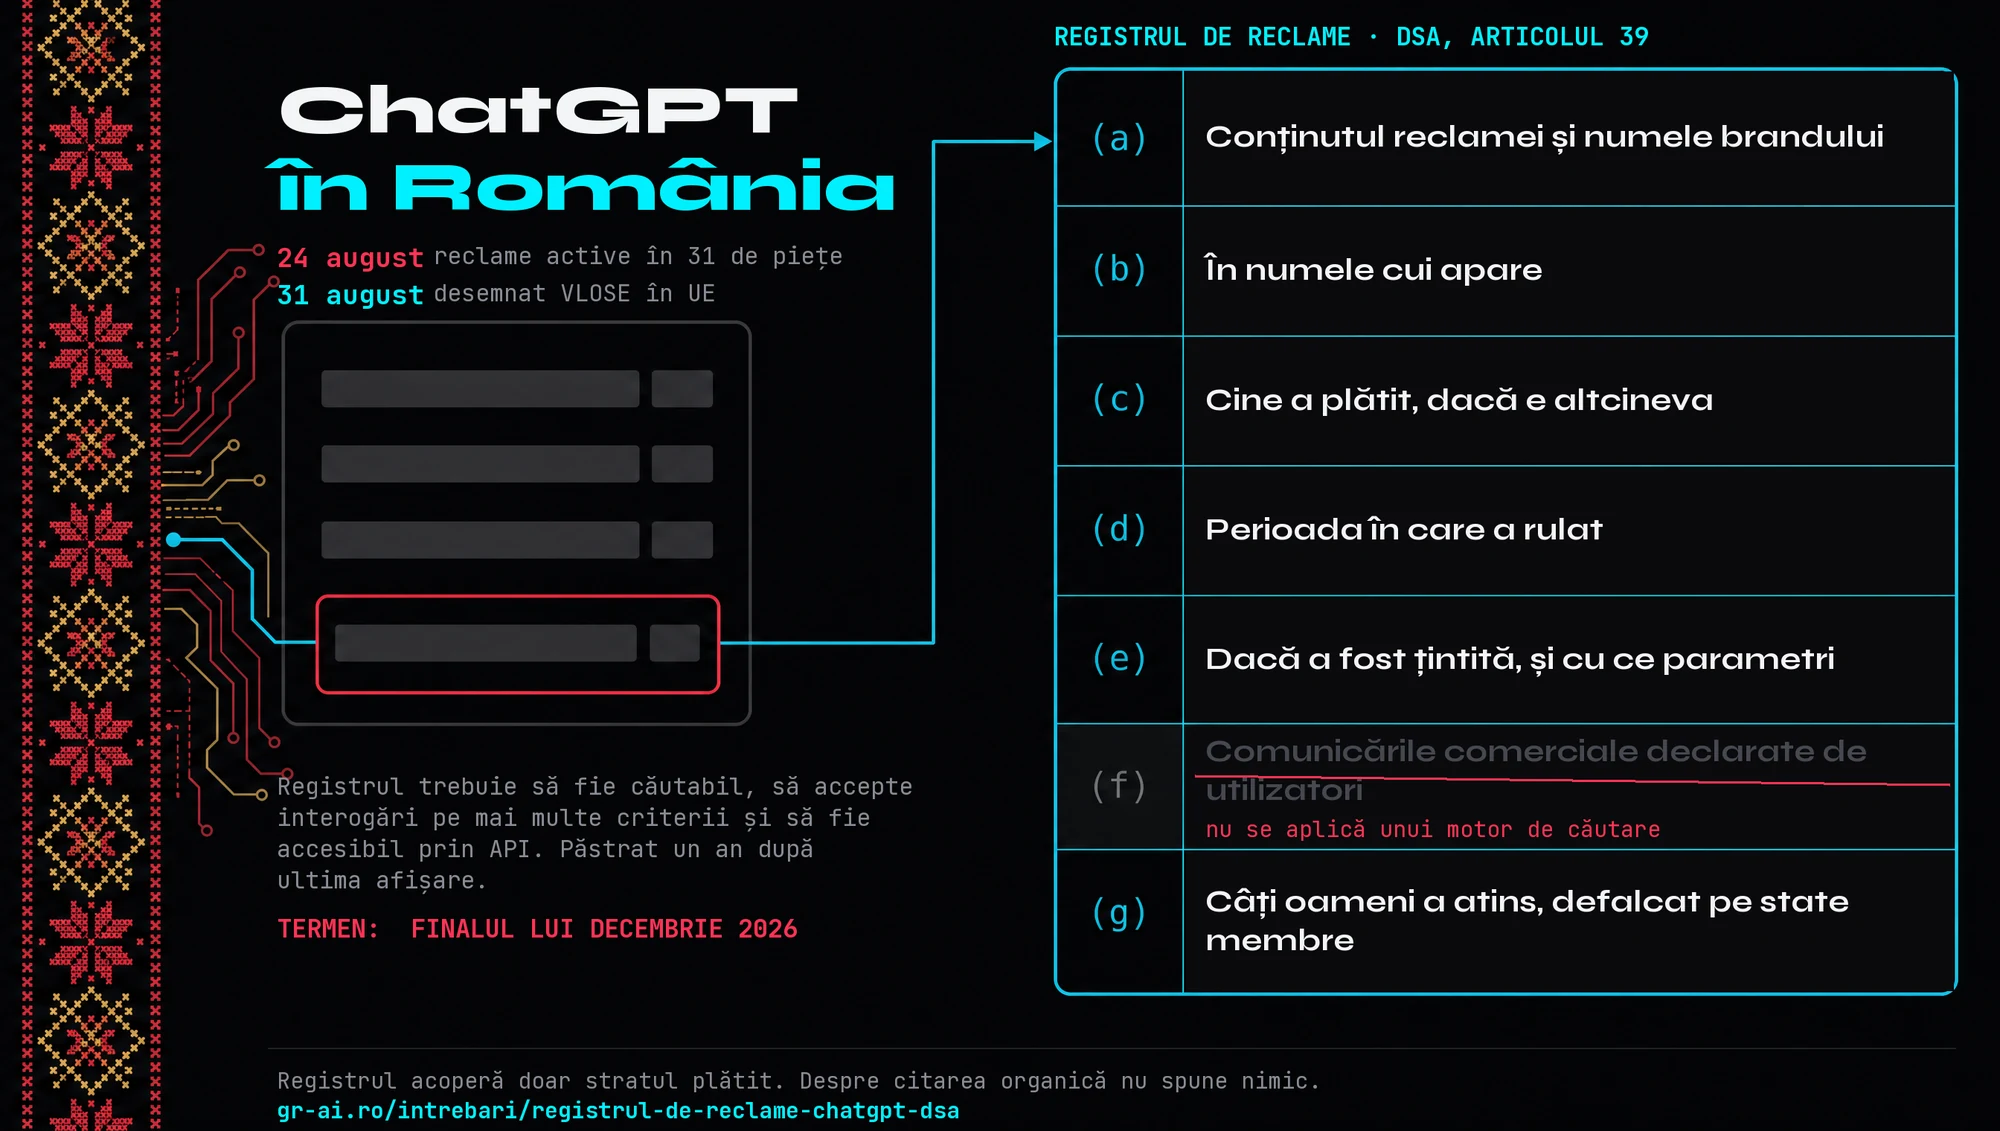
The two dates
- 24.08
ChatGPT starts showing ads in Europe
Across 31 European markets: the 27 EU member states plus Iceland, Liechtenstein, Norway and Switzerland. Ads appear only to users on the free and Go plans; anyone paying for Plus, Pro or Business does not see them.
- 31.08
The European Commission designates ChatGPT a very large online search engine
The threshold is 45 million monthly users in the Union. The reason it lands as a search engine rather than a platform is that ChatGPT searches the web and summarises results. The Commission's page states that a designated service has four months to comply, so the obligations bite from the end of December 2026.
The Romanian press covered the second one, correctly and at length. What we did not find written anywhere is what emerges when you put both on the same page.
What Article 39 requires
The Digital Services Act treats very large platforms and very large search engines separately, but Article 39 names both. The text says that providers of very large online platforms or of very large online search engines that present advertisements have to compile and make publicly available a repository, in a dedicated section of their interface.
Three details in the same article change its usefulness entirely:
- Searchable, on multiple criteria.
Not a PDF report published quarterly. A tool that accepts combined queries.
- Accessible through an API.
Meaning it can be queried automatically, at intervals, without anyone clicking through an interface.
- Kept for a year after the last impression.
The repository covers the whole period the ad ran, plus twelve months after. The history does not vanish when the campaign stops.
The fields that become public
Paragraph 2 of the article lists seven letters, from (a) to (g), as the mandatory minimum. The letter on the left is the one in the legal text, so you can check every row against the source. Six of them apply to a search engine. The seventh does not, and it is worth explaining why.
- (a)
The content of the advertisement, including the name of the product, service or brand
You see the exact message, not a description. What a competitor promises to someone who is not seeing you.
- (b)
The natural or legal person on whose behalf the advertisement is presented
The brand behind it, even when the ad does not name it obviously.
- (c)
Who paid for the advertisement, if that is someone else
Separates the client from the agency and shows who is actually funding a campaign.
- (d)
The period during which it was presented
How long a campaign runs and whether it repeats. An ad that runs for months is an ad that works.
- (e)
Whether it was intended to be presented to specific groups, and the targeting parameters
Who your competitor thinks is worth paying for. This is the most expensive item on the list.
- (g)
The total number of users reached, broken down by member state where applicable
How many people in a given country. Not a vendor estimate, but a figure reported under legal obligation.
Letter (f), and why we took it out of the list
Letter (f) asks for the commercial communications identified pursuant to Article 26(2). If you go and read that article, it describes a feature through which the users of a platform declare that content they uploaded is a commercial communication. That is the sponsored-content disclosure, for people posting on a social network.
A search engine has no users publishing content, so there is nothing to declare. The letter stays in the text, but in ChatGPT's case it produces nothing. It is the seam left by the fact that Article 39 was written with platforms in mind, and applying it to an AI search engine shows the stitching.
What you can do with this
If you sell something in a niche where competitors are paying for ads in ChatGPT, the repository answers questions that today either cost money or have no answer at all.
- 1Who is actually buying.
Not who says they are investing in AI, but who paid, for what, and for how long.
- 2What message they use.
The exact text of the ad, not what they say in interviews.
- 3Who they target.
The targeting parameters show which segment they think is worth paying for. It is the most expensive information on the list, and it becomes free.
- 4How big the market is.
The number of users reached, broken down by state. The first figure about AI advertising in a given country that does not come from a vendor.
- 5What worked and what stopped.
A campaign that runs for months is working. One stopped after two weeks probably is not.
What the repository will not tell you
The part worth remembering is what is missing.
The repository covers advertisements. That is, the paid layer. It says absolutely nothing about why ChatGPT cites one source and not another when it composes an ordinary answer, with no ad in it.
These are two different mechanisms, and confusing them is the predictable mistake of the coming months. A brand can appear in the repository because it paid, without ever being cited organically. Another can be cited constantly without having bought anything. The transparency Article 39 brings does not extend to the second case.
Other articles in the same regulation require the main parameters of recommender systems to be explained, and data access for researchers. How much of source selection becomes verifiable through those remains an open question, and we are not going to pretend we know the answer before the first document exists.
What is worth doing before December
One thing, and it is cheap. When the repository opens, it will show what happens from that point on. What is useful is having something to compare it against.
- 1Write down what you see now.
Open ChatGPT on a free account, ask the questions from your niche, save screenshots of the ads that appear. It takes an hour a month.
- 2Keep the ad-free answers too.
The same questions, who gets cited organically. That is the data the repository will never give you.
- 3Date every measurement.
Without a date, a screenshot proves nothing three months later.
In December, whoever has measurements from September will be able to say what changed. Whoever does not will read the repository like a photograph with no context.
Where the data on this page comes from
- The designation and the deadline. The European Commission's page on DSA designations, which states that a designated service has four months to comply.
- The repository requirements. The text of Article 39 of the Digital Services Act, paragraphs 1 and 2. The regulation has official versions in every EU language.
- The ads in Europe. OpenAI's announcement about the expansion into the 31 European markets, with the date it went live.
We have put no percentage about ad or citation performance on this page. Studies are circulating, some of them good, but we did not measure them ourselves and we do not repeat numbers we cannot verify.
Share this article
Further reading
- Why my competitors show up in AI and I do notThe organic side, the one the repository does not cover
- How do I check whether an AI can read my siteThe thirty-second check, before any advertising budget
- All the questions explainedIn the order it makes sense to read them
- If you want the baseline measurement taken nowSo that in December you have something to compare the repository against