AI Agents Read Your Website. The Files Made Just for Them, Hardly at All
by Cătălin Popa · updated 2026-10-06
Everyone is talking about files for AI right now: llms.txt, Markdown versions, new drafts filed with the IETF. Meanwhile, the first large experiment on what agents actually read came out on 28 September, and its conclusion is less spectacular and more useful: what matters is your ordinary page, not the new file. I read the study down to its tables, set the log measurements next to it, and checked 30 websites of small businesses in Romania.
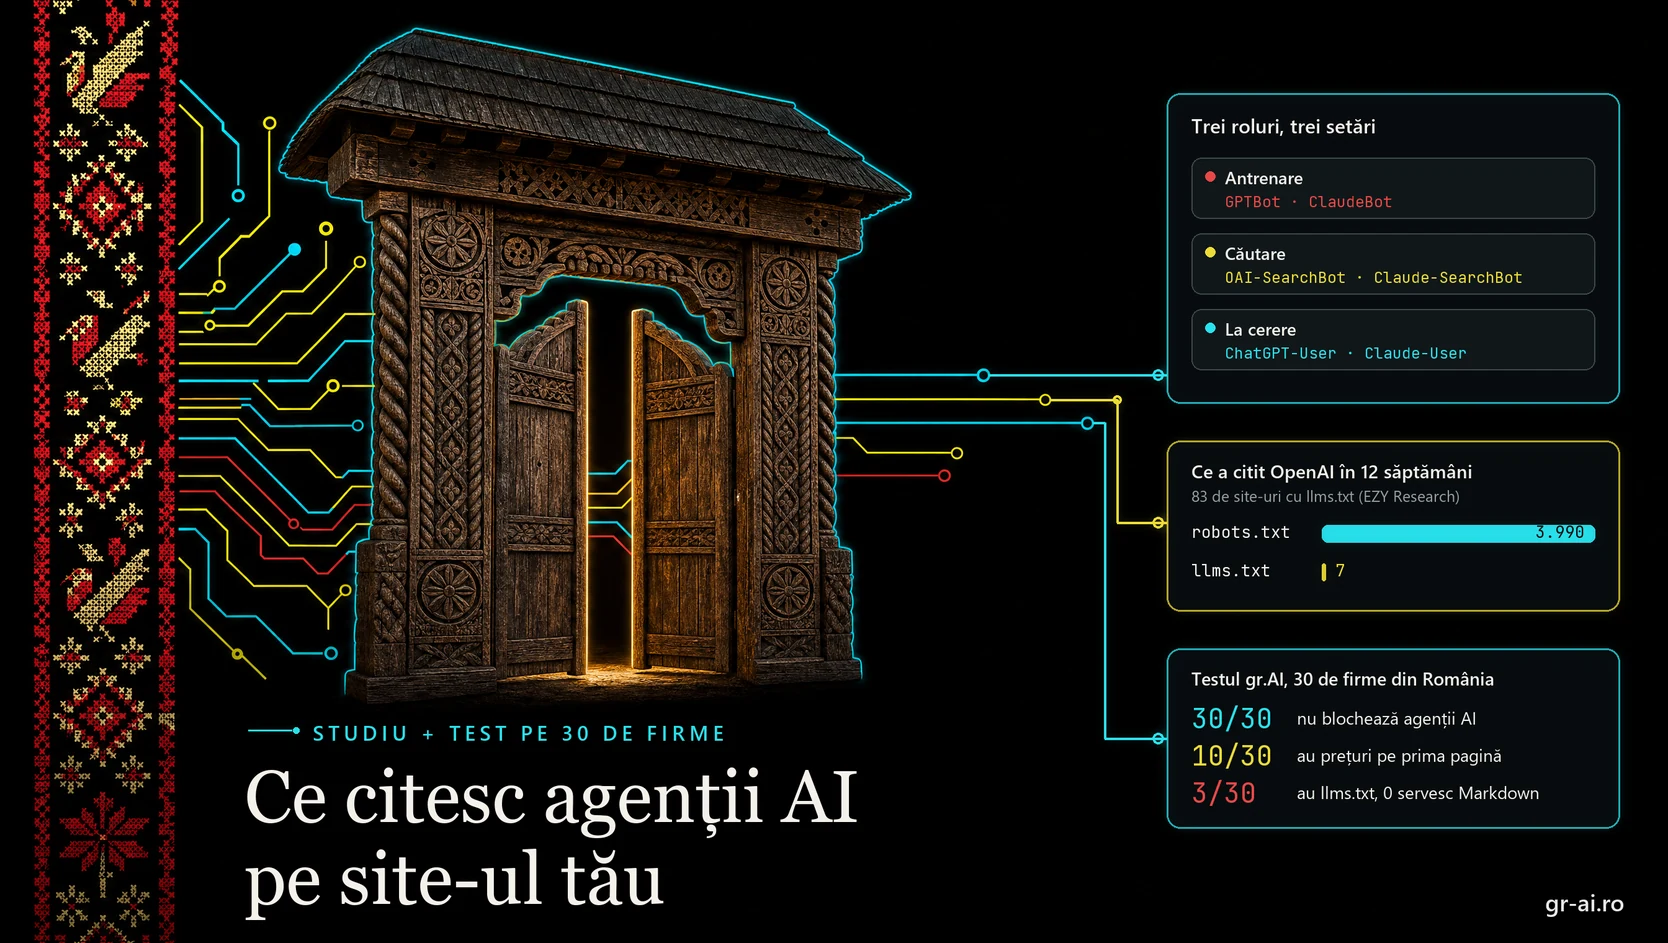
What do AI agents read when someone asks about your company?
AI agents that answer questions about a company read its ordinary pages at the very moment of the question and build the answer from what they find there. In an experiment on 1,056 companies, those with websites agents can easily read were clearly recommended almost twice as often, and when the agent could not read the site it answered anyway, from other sources, and more often left out exactly the facts that were asked for. Files made especially for AI, such as llms.txt, are rarely requested by the big platforms' crawlers, though, and Google says Search does not need them. The priority remains a site that lets agents in and puts the essential information right on the page. We checked 30 businesses in Romania: none blocks AI agents in robots.txt and almost all have text on the page, but only 10 have prices on the home page, 3 have llms.txt and none serves Markdown.
Who actually visits your website
OpenAI and Anthropic split their bots into three roles, and the difference matters more than any new file. One collects text to train models. Another indexes for the assistant's search. The third reads a page at the very moment a person asks a question. The study below measures exactly that third role.
- Training
GPTBot · ClaudeBotBlocking keeps your future content out of training data.
- Indexing for search
OAI-SearchBot · Claude-SearchBotBlocking takes you out of the assistant's search results.
- Reading on the user's request
ChatGPT-User · Claude-UserOpenAI says that, since these are actions started by a person, robots.txt may not apply. Anthropic says Claude-User respects it too.
The settings are independent: you can refuse training and still allow search and on-demand reading. But a blanket “block AI bots” rule, in robots.txt, in the firewall or in the CDN, cuts all three at once, often without anyone consciously deciding it.
What the largest experiment so far showed
Four researchers from ora research published an experiment on 1,056 companies on arXiv on 28 September: 37,927 sessions, with four agent and model combinations (Claude Agent SDK with Sonnet 4.6, Claude Code with Haiku 4.5 and two GPT-5.4 variants with Tavily search). Each agent got the same three types of questions about a specific company: pricing, features, how to get started. The companies were split into two groups, by how easily an agent can read their website, and paired on fame and on presence in training data.
Easily readable sites, compared with the rest:
- of the answer text comes from the company's pages78% vs 58%
- of answers clearly recommend the company, 1.9 times as often20% vs 11%
- of answers say the agent could not access the site3.6% vs 15.9%
- of sessions hit errors or anti-bot walls15.8% vs 33.5%
- of the answer text comes from the model's memory7% vs 10%
Three limits, stated plainly. The questions always named the company, so the study says nothing about open questions like “the best X in city Y”, where it is decided whether you get found. The score that separates the groups belongs to the authors' company and is a composite: content without JavaScript, structured data, llms.txt, Markdown, anti-bot rules, all together, with no separate effect for each. And the sample is in English, dominated by SaaS and commerce. The clearest signal in the paper is also the most mundane: unprepared sites blocked the agent twice as often.
The discovery step is touched by another study, published on 19 September by Benjamin Tannenbaum, on almost 35,000 GPT and Gemini answers to questions without the brand name. When the engine cited the company's own domain, the brand was mentioned in 49% of answers on GPT and 58% on Gemini, against 3 to 4% when it did not. It is an association, not a cause, and the author sells measurement tools. But it fits the rest: your site matters even when nobody searches for you by name.
The typical failure is silence, not lies
When the agent cannot read the site, it does not stop. It answers anyway, from searches and from other people's websites. And the difference is not in what it makes up: facts stated wrongly only rise from 4% to 6%. It is in what is missing: requested facts left unmentioned rise from 29% to 45%.
The biggest gain, when the answer comes from the site, is on pricing: 60% of the requested facts correct, against 37% when the answer comes from the web. On setup questions the gain is zero, because the information sits in hard-to-find documentation. The comparison is made on the same company, with the same agent and the same type of question.
A site the agent cannot read does not take you out of the answer. It leaves you in it, described by others, with pieces missing.
The files made for AI: who reads them
Here the data points the other way. Four independent measurements, from real logs:
- The Arsentev draft, 5 October.
A publisher put the file on their site and counted: in the 3 days with the file installed, crawlers read robots.txt 698 times and the context file never. The author states the limits himself: a single publisher, bot identities unverified.
- EZY Research, July.
On 83 websites, over 12 weeks, OpenAI read robots.txt 3,990 times and llms.txt 7 times. Anthropic: 3,120 against 9. PerplexityBot: 775 against 0.
- Ahrefs, June.
Across 137,210 domains analysed, 97% of the existing llms.txt files got no request at all in the whole of May.
- Evil Martians, July.
On a single site, over two months, ChatGPT-User requested HTML 99.9% of the time. Only the coding agent Claude Code asked for Markdown, in 76% of its requests, through the Accept header, not through llms.txt.
Google also writes, in its guide to AI features in Search, updated on 10 July, that you do not need new machine-readable files, AI text files or Markdown to appear there, and that such files neither help nor hurt. Three of the four measurements come from companies that sell tools or services on the subject, so they deserve a careful read. But they all point the same way.
Agents mostly read the HTML of your pages. The new file remains, for now, an accessory.
The standards, still bubbling
The problem is how an agent finds out that the file exists, and it has three answers, none of them standard. llms.txt v2, from 10 August, links pages to the file with ordinary link relations: describedby towards llms.txt and alternate towards the Markdown version. A draft filed with the IETF by Evgenii Arsentev, revised on 5 October, wants a fixed address, /.well-known/llm-context, a new relation and a new line in robots.txt. A second one, by Andrei Nicolae Besleaga, from 30 September, proposes a single JSON document listing all of a site's knowledge files, each of which can carry its SHA-256 fingerprint.
Both are individual drafts: anyone can file one, and the IETF says explicitly that they have no standing in the standards process. They are worth watching, not rushing to implement. Both get one thing right: they require the agent to treat the file's content as data, never as instructions.
WordPress: Markdown for agents and a new door for actions
The official AI plugin for WordPress, version 1.4.0 from 5 October, with over 50,000 installs, has an experiment called Markdown Feeds that serves posts and pages in Markdown. It is off by default. The Markdown versions get noindex but no canonical, and negotiation through the Accept header is a second checkbox, also off, with a cache warning. The plugin has no Romanian translation yet.
The MCP Adapter 0.7.0, which entered the official directory on 2 October, is something else: it is not about visibility, it is about actions. It lets an agent execute functions on the site. The default server starts by itself on activation and, by default, any logged-in user with read capability can connect, which includes a plain subscriber. On a shop where every customer has an account, the exposed functions need checking. For companies with NIS2 obligations, this is an inventory item, not a marketing one.
Our test: 30 businesses in Romania
From OpenStreetMap, the same open map as in the hotel test, I took the shops, offices and workshops with a listed website in six cities: Bucharest, Cluj-Napoca, Iași, Timișoara, Brașov and Constanța. I removed the chains tagged on the map and the duplicates, which left 1,488 places with a website. I shuffled the list at random and took five working websites of their own from each city. On each, I read the home page without JavaScript and robots.txt, looked for llms.txt and requested the page in Markdown, through the Accept header, on 6 October 2026.
To get to 30 I drew 46 points from the map. For 8, the website did not respond even on a second attempt. Another 7 were public institutions, an embassy, a political organisation or a mall, which I removed, because the test is about businesses. For one, the company's name did not appear on the site. The remaining 30 are mostly small businesses, from a bookshop and a pastry shop to a shoe repair workshop and a translation office, but also a few large ones, such as DIGI.
What I found on the 30 websites:
- block no AI agent in robots.txt30 of 30
- have text on the page without JavaScript29 of 30
- mention their city on the home page26 of 30
- have their phone number on the home page17 of 30
- have prices on the home page10 of 30
- have structured data about the business3 of 30
- have llms.txt3 of 30
- serve Markdown on request0 of 30
The picture is almost the opposite of the industry conversation. The door is open: no robots.txt blocks AI agents, and 29 of 30 pages have text without JavaScript. The new files are rare: 3 of 30 have llms.txt, one generated automatically by Yoast, and none serves Markdown. What is missing is exactly what an agent looks for: only 10 of 30 have prices on the home page, 17 have their phone number there, and only 3 have structured data about the business. Prices may sit on other pages, but an agent that starts from the home page has to reach them, and prices are precisely the facts where the ora study found the biggest gain when the answer comes from the site.
The limits, stated plainly: a small sample, drawn from businesses that have a website on the open map OpenStreetMap; only the home page, checked once, without JavaScript. Robots.txt does not catch blocks in the firewall or the CDN, which we did not test, because we do not pretend to be someone else's bots. We publish the method and the aggregate figures, not the list of businesses.
What to do, in order of evidence
The order follows how strong the evidence is, not how new the topic is.
- Let in the on-demand and search agents.
Check robots.txt, but also security plugins, your host's firewall and the CDN. Decide separately: training (GPTBot, ClaudeBot), search (OAI-SearchBot, Claude-SearchBot), on-demand reading (ChatGPT-User, Claude-User).
- Put the answer in the initial HTML.
Prices, packages, opening hours, service area, terms: all of it must exist in the page as downloaded without JavaScript. The simple test: fetch the page without a browser and look for the number.
- Publish the facts the buyer asks for.
The typical failure is omission. If the price is not on your site, the agent takes it from somewhere else or does not mention it at all.
- Keep structured data, without magical expectations.
Google says there is no special markup for AI, but still recommends structured data for SEO. Its value is consistency: the same data everywhere.
- llms.txt: optional, small and clean.
It is cheap, and on WordPress Yoast SEO or AIOSEO can generate it. Link it from your pages, keep it short, with nothing that sounds like an instruction, and do not promise anyone traffic from it.
- Markdown: only if you have a reason.
The documented benefit is with coding agents. Before you switch it on, check that your cache and CDN respect the Vary: Accept header.
- MCP only with a clear use case.
And with the list of exposed functions checked after every new plugin you install.
- Measure in your own logs, per agent.
Google Analytics does not see visitors without JavaScript. Also check IP addresses against the lists published by OpenAI and Anthropic, because a User-Agent can be faked: in Arsentev's logs, about a third of the “crawler” requests bypassed the CDN and none came from the operators' published addresses.
Frequently asked questions
- Do I need llms.txt to show up in ChatGPT?
- There is no evidence that it helps. Published measurements show that the big platforms' crawlers request it very rarely, and Google says Search does not need it. You can have one because it is cheap, but it is not the priority.
- Do AI agents see content loaded with JavaScript?
- As a rule, no. Most of them download the page without running JavaScript, so prices or descriptions loaded afterwards can be completely missing from what they read. The essential information must be in the initial HTML.
- If I block GPTBot, do I disappear from ChatGPT?
- Not necessarily. At OpenAI, GPTBot is about training, OAI-SearchBot about appearing in ChatGPT search, and ChatGPT-User about visits made at a user's request. The settings are independent and decided separately.
- What is the Markdown version of a page, and do I need it?
- It is a clean text copy of the page, for programs. Coding agents already ask for it, but for a company website the benefit has not been shown, and every version is one more address to manage.
- Is it dangerous to install MCP on WordPress?
- MCP lets agents execute actions on the site, not just read it. By default it requires a logged-in user, but the bar is low, so check which functions are public and switch off the default server if you do not use it.
Where the data comes from
- The ora research study. Finder, Elovic, Shalev and Yosef, “AX is the New AEO”, arXiv 2609.34951, 28 and 29 September 2026, read in full, with the tables.
- The Tannenbaum study. “From Prompt to Recommendation”, arXiv 2609.23162, 19 September 2026.
- The drafts filed with the IETF. draft-arsentev-llm-context-discovery, the revisions of 11 September and 5 October 2026, and draft-besleaga-agentic-knowledge-wellknown, 30 September 2026, both individual drafts with no IETF standing.
- llms.txt v2. llmstxt.org and its changes page, the 10 August 2026 version.
- The log measurements. Ahrefs (15 June 2026, across 137,210 domains), EZY Research (27 July 2026, on 83 websites) and Evil Martians (21 July 2026, one site, two months).
- Google Search Central. The guide to optimizing for generative AI features in Search, updated on 10 July 2026.
- OpenAI's and Anthropic's documentation on bots. The pages on GPTBot, OAI-SearchBot and ChatGPT-User, and on ClaudeBot, Claude-SearchBot and Claude-User.
- WordPress. The official AI plugin 1.4.0 (5 October 2026), with the Markdown Feeds experiment code read at the released version, and MCP Adapter 0.7.0 (2 October 2026), with the default server documentation.
- Our own test. 30 businesses in six cities, drawn at random from OpenStreetMap and checked on 6 October 2026, read-only, without JavaScript, with a User-Agent that says who we are.
Share this article
Further reading
- How do I check whether an AI can read my siteThe test from this article, done yourself, in ten minutes
- What ChatGPT's new hotel feed means for a hotel in RomaniaThe same kind of test, on 30 hotels and guesthouses
- What structured data actually does for AIWhat still holds when the new files do not help
- If you want the check run on your own siteAccess, for every bot role, and what an agent finds on the page